
- Brand
- Unknown
- Category
- Pending
- Primary Subcategory
- Pending
Integration details
Description
Ayzeo shows you how AI assistants talk about your brand. Ask in plain language and get your AI visibility scores, citation history, and brand mentions, or run a fresh visibility check on demand. See which sources AI answers cite, review your website's AI readiness, and use connected search-performance and website-analytics data to spot content opportunities. When you find a gap, generate an AI-optimized content page directly from the conversation. One sign-in connects all your Ayzeo projects. Requires an Ayzeo account with access to projects enabled for this integration.
- Integration type
- Plugin
- Verification status
- Not applicable
- Platform
- ChatGPT
- Category
- Pending
- Primary Subcategory
- Pending
- Secondary Subcategories
- None listed
- Brand
- Unknown
- Access
- Account required
- First tracked
- 2026-10-17
- Tool count
- 21
- Geography
- US
The broad Category that contains the Primary Subcategory.
The Primary Subcategory used for this profile’s headline score.
Other Subcategories where the Integration is listed.
 Agent Discoverability
 ChatGPT Plugin Discovery Score
Your score is coming
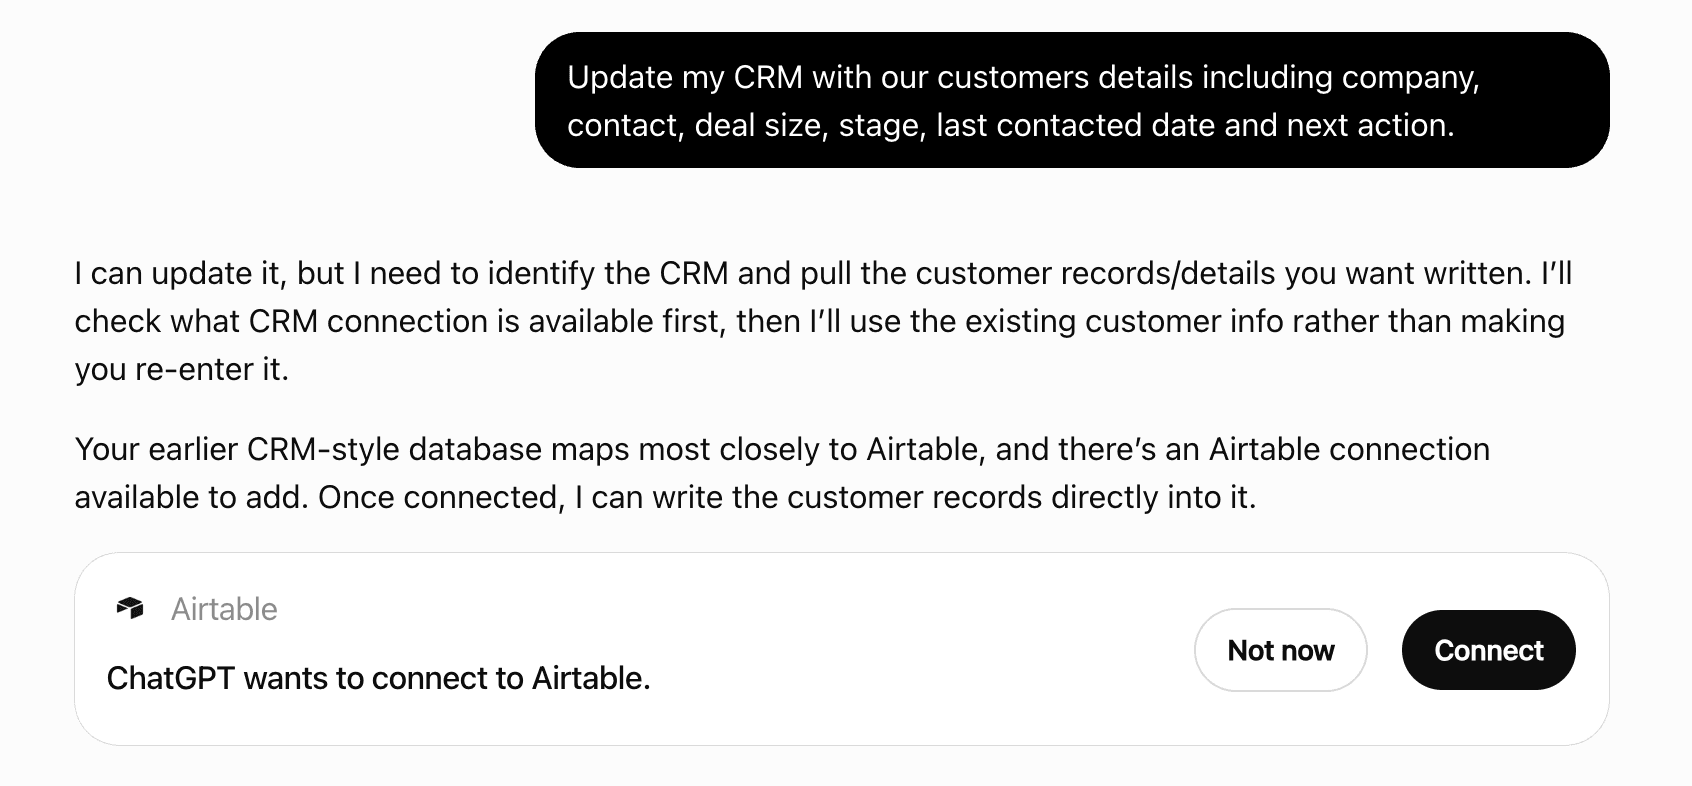
ChatGPT now suggests Plugins on its own when they match a user's request.Your Plugin Discovery Score measures how often yours appears, and it will show here as soon as it’s ready.
What discovery looks like
Get alerts for Ayzeo
Get updates when Ayzeo’s Discoverability Score or category rank changes.
Competitive lineup
21 tools agents can invoke
Generates a new content page for the given query using the N8N content-page pipeline, persists it, and returns the ContentPage id + generated SEO elements + edit URL. Counts against the project apiLimiter quota. Requires an active paid subscription on the project owner.
create_content_page_from_query
Returns Google Analytics 4 traffic segmented by AI referrer source (ChatGPT, Claude, Perplexity, Gemini, DeepSeek, Grok, Copilot, You.com, Phind, Kagi, OpenAI API apps) plus organic/direct/social baselines. Per source (bySource): sessions, new users, engagement rate, bounce rate, avg session duration, key events (conversions = all GA key events summed, an event count, not converting sessions), the project's chosen key event (primaryKeyEvents), ecommerce purchases, purchase revenue (in currencyCode) and add-to-carts; topLandingPages lists the pages AI visitors land on. paidAI covers ChatGPT Ads separately (never counted in totalAISessions or aiTrafficPercentage): ads vs organic ChatGPT outcomes, a daily split, the campaign table (utm_campaign / utm_id / utm_content) and untaggedClicks, i.e. ad clicks that arrived without UTMs and are credited to other sources (an estimate). trafficSpikes lists days where an organic AI source looks like bot traffic: reason "burst" (far more sessions than its usual day, mostly bounced) or "engagement_drop" (more sessions and a bounce rate several times its usual one). sampledDates lists days GA answered from a sample of the traffic (estimates; recent ones are re-fetched by later syncs). All rates (engagementRate, bounceRate, baselineBounceRate) are percentages 0-100. When the detailed read fails, bySource falls back to sessions, new users, conversions, purchases and revenue only. Requires GA integration. No distinct-user (unique visitor) count is available: GA4 reports it per dimension row and it cannot be summed over a date range, so only additive metrics are returned.
get_ga_ai_traffic
Returns Ayzeo's curated GEO playbook: recommended tactics for improving brand visibility in AI search engines, maintained as per-model sets (ChatGPT, Claude, Perplexity, Grok; Gemini/AI Overviews are covered by classic SEO). Pass `engine` to get that engine's resolved set: engine-specific texts and priorities merged in, sorted from high to low priority, each recommendation stamped with last_updated and the model version it was validated against. Omit `engine` for the full playbook (base recommendations plus per_engine override blocks and the per-engine model-version map) so the calling agent can reason across engines itself.
get_geo_recommendations
Headline content-prioritization tool. Returns the top-N highest-ACOS (Ayzeo Content Opportunity Score) GSC queries for the project. ACOS is a 0–100 deterministic composite score combining 9 weighted dimensions: strikingDistance (0.20), ctrGap (0.10), impressionVolume (0.15), momentum (0.10), positionTrend (0.05), contentGap (0.15), brand (0.10), longTail (0.05), trafficUplift (0.10). The tool surfaces the per-dimension scores, weights, and underlying GSC metrics (impressions, position, trend deltas, topPage) so the AI can articulate its own reasoning. Each item also flags hasDedicatedContentPage / existingContentPageId for clean branching between "create new" vs "enhance existing". Requires GSC integration to be connected and synced. Implementation note: the underlying aggregation pulls the top 500 queries by 30-day impressions before scoring, so projects with >500 low-impression queries may miss some long-tail opportunities — tune minImpressions/maxPosition to re-shape the pre-filter if needed.
get_gsc_opportunities
Paginated raw aggregated GSC query data (unscored) for ad-hoc AI filtering. Sortable by impressions, clicks, ctr, or position. Requires GSC integration.
get_gsc_queries
Link health of the project's OWN-domain URLs that AI answers exposed, the same data as the URL Health page. layer "answers" (default) = links shown inside the answer text, the ones a reader sees and clicks; layer "all" adds pages the models opened or consulted while answering (machine-side, never shown to a reader). Each URL carries the measured status: ok (200), redirect (finalUrl + redirectChain), dead (404/410), soft404 (the page answers but its content says not found, evidence-based), unconfirmed (missed one check, being rechecked, NOT broken yet), unreachable (timeout, server error, blocked by the site or robots.txt, NEVER counted as broken) or pending (not checked yet). broken is true only for dead and soft404, each confirmed by two separate checks at least 15 minutes apart. possibleFix is a pattern-based candidate that answered when checked (e.g. a dropped path segment, or the page's structure in the site's other markets): always present it as a possible fix to verify before redirecting, never as the confirmed fix; possibleFix.rule is a wildcard redirect when several broken URLs share one transformation. answers = distinct answers in the window that showed the URL in their text (layer "answers"), or that showed, opened or consulted it (layer "all"); prompts = distinct prompts, counted the same way; both count live (still tracked) prompts only. Sorted by answers, most-shown first. totals = per-status counts of every URL in the window and layer (not only the returned rows); total = rows matching `status` before `limit`. status: "dead" = broken only, "redirect", "unreachable", "ok", or "all" (default, includes unconfirmed and pending). hostsBlocked names hosts the latest checks could not check, with a reason (a refusal, timeouts, server errors, an unreadable robots.txt or a robots.txt Crawl-delay too long; their rows keep their last measured status), and the notes say which of them allowlisting the user agent fixes. Read-only: it never starts a check; checks run after the project's scans. Use for "which links does AI show to our site that are broken", "what should we redirect", and the broken-links section of a report.
get_url_health
Returns brand-mention data from AI answers aggregated per brand with sentiment counts (positive/neutral/negative) plus the 25 most recent individual mentions. Gives the AI a complete picture of the brand's positioning before recommending content.
get_brand_mentions
Returns recent prompt citation history across all AI models (ChatGPT, Claude, Perplexity, Gemini, DeepSeek, Grok) including citation counts, URL visits, mentionPosition (order the brand was named in that answer, 1 = first, null = not mentioned) with mentionedBrandCount, dominant sentiment, searchTerms (the web searches the AI ran for that answer — the query fan-out), citedUrls (pages on the project's own domain/channels the AI opened) and visitedUrls (every page the AI actually opened, competitors included). Each row carries promptDeleted: true when that prompt has since been removed from tracking (its history is kept); promptText is null only for runs whose prompt was hard-deleted before soft delete existed.
get_citation_history
Aggregates the sources behind the AI answers: which domains the AI models' web searches surfaced across ALL the project's prompts in the window (latest run per prompt+model). Returns up to 60 domains ranked by citations, each with class ('own' = the project's own domains, 'pinned' = a tracked competitor, 'other' = third-party such as directories, review sites, press — the quickest listing wins), citations, prompts (distinct prompts it appeared for), answers (distinct answers whose search results included it) and answerShare (answers as a % of answersTotal, the number of latest answers in the window), models, and sourceType where classified, plus a mix summary, totalCitations and answersTotal. Pass `domain` to drill into one domain: its most-cited URLs (title, citations, answers, answerShare, path bucket), the detail's own answersTotal denominator, and the prompts driving them. Pass `view: "pages"` for the page-level list instead: URLs across every domain ranked by citations (default 100 rows, `limit` up to 300; fields url, domain, title, class, sourceType, citations, prompts, answers, answerShare, models, bucket, unresolved for opaque Google redirect links) plus totalUrls (distinct URLs before the cap) and a `buckets` page-type mix computed over the full cached top-300 list, not only the rows returned under `limit`. Pass `url` to drill into one exact page: its citations, answerShare and the prompts whose answers consulted it (takes precedence over `domain`). Windowed (default 30d; presets up to "all", or startDate+endDate). Use for "which sources do AI answers rely on", "where can I get listed", and content-gap analysis against competitor pages.
get_citation_sources
Returns the project's already-generated content pages with their query, template, enhancement state, placement status, SEO HTML, and edit URLs. Use before recommending a new page to check whether one already exists.
get_content_pages
Fetches the latest stored advanced website/technical analysis for the project. Returns scorePercent plus results.checks (per-check booleans across SEO, structured data, AI readiness, robots/llms.txt, security; false = open issue, null = not measured), results.performance (LCP/CLS/TBT), results.scannerDetails (per-check evidence), results.detailedRecommendations, and results.suggestedSnippets (ready-to-paste JSON-LD, llms.txt, and meta-tag suggestions generated for this site). Check createdAt for staleness before deciding whether to trigger run_website_analysis.
get_analysis_results
Returns project name, domain, plan tier, and basic settings.
get_project_info
Returns aggregated project stats. Windowed (default 30d; pass timeRange or startDate+endDate — two calls with shifted windows give period-over-period comparisons): ownBrand summary (mentionRate, urlCitationRate = real citation rate, visibilityShare, avgMentionPosition, sentiment counts), brandRanking (top 20 brands incl. competitors — re-sort by mentionRate client-side for "top competitors by mention rate"; list order is the project's ranking config), and brandRankingByModel (per-model slices, top 10 each — use for per-model breakdowns; visibilityShare there is computed within that model's slice, not the merged list). All-time: totalPrompts, totalCitationResults, totalBrandMentions, byModel raw run/citation counts, latest analysis score. avgMentionPosition = own brand's rank among brands mentioned in AI answers, lower is better, branded prompts excluded.
get_project_stats
Project-wide summary with two halves whose counting differs on purpose. `pages` is ALL-RUN: every stored answer in the window counts (same-run retries once), unlike get_citation_sources, which reduces to the latest run per prompt+model. It lists the most- and least-visited pages (visited layer = URLs the AI actually opened; distinct from the cited/search-results layer), each row with url, domain, class (values "own", "pinned" = a tracked competitor, "other"), visits (total opens), answers (distinct answers that opened THIS url), answerShare (that answers count as % of answersWithVisits, the answers that opened any page at all; Google AI Overview never exposes visited pages, so answersTotal is the wrong denominator), prompts, models and path bucket, plus totalUrls and the least-list floor (minAnswers: opened in at least 2 distinct answers). `brands` is NOT all-run: it reuses the same curated period-average ranking the dashboard brands table shows (per-day share of prompts mentioning the brand from the day's latest runs, averaged over days with results and across models), resorted into most- and least-mentioned; the least list requires mentions for at least minPrompts distinct prompts so one-off names are not the headline. Brand rows carry mentionRate (rounded to one decimal, so a rarely mentioned brand can read 0 while promptsMentioned is positive), avgMentionPosition, promptsMentioned, visibilityShare, sentiment and isProjectDomain. Windows: presets incl. 6m/1y/all (all = full stored history, window starts 2020-01-01), or startDate+endDate; `model` narrows to one AI model. Use for "which pages do AI models visit most/least", "which brands dominate or barely appear", and period-over-period report tables (two calls with shifted windows).
get_project_summary
All-run analytics for ONE tracked prompt in a window (default 30d): every successful stored run, same-run retries counted once, NOT the latest-run-per-model snapshot list_prompts returns. Returns searchQueries (the exact web searches the models ran while answering — the query fan-out — deduplicated per answer), recurringPhrases (2- and 3-word phrases DERIVED from those queries and appearing in at least two answers: analysis output, never searches anyone ran), recurringBrands (brands named in the answers, counted once per answer and grouped like the Brand Industry Ranking, so spellings and sites of one brand are one row; each flagged isOwnBrand; a competitor's context-only mentions are excluded, while the own brand counts every answer with brand detection that names it, as ownBrandMentioned does; branded prompts contribute no position), a coverage-aware summary, per-model run counts, and a paged answer archive. Read the shares carefully: shareOfAnswersWithQueryCapture and shareOfAnswersWithBrandDetection are percentages of the answers where that field was CAPTURED (the sibling answersWithQueryCapture / answersWithBrandDetection is the denominator), not of every run — a query seen in 3 of 3 answers that captured queries is 100% of those, even if 30 runs exist. capturedQueries is null when the surface cannot expose the fan-out and [] when capture worked and the model ran no search; never read null as zero. Answers are paged 20 at a time (pass page); resultId identifies a stored run for dashboard links and is not an input to another tool. Use it for 'what do the models actually search for this prompt', 'which brands keep showing up in this prompt's answers', and before recommending content for one prompt.
get_prompt_insights
The web searches the AI engines ran before answering, across EVERY tracked prompt of the project in a window (default 30d): every stored run, same-run retries counted once, each query counted once per answer. Returns searchQueries (the exact queries with answers, prompts that triggered them, shareOfAnswersWithQueryCapture, models, first/last seen and the brands named inside the query text, your own brand flagged isOwnBrand), recurringPhrases (2- and 3-word phrases DERIVED from those queries and seen in at least two answers: analysis output, never searches anyone ran), a coverage-aware summary and a per-model breakdown. Read the shares carefully: they are percentages of answersWithQueryCapture (answers whose own searches were stored), not of every run. Perplexity and Google AI Overview do not expose their searches, so their answers are eligible without query capture. This is the project-wide counterpart of get_prompt_insights' searchQueries. Use it for 'what do the models actually search for across my prompts', to pick the queries and phrases new content should target, and with promptIds to compare prompt groups.
get_search_queries
Returns saved prompts for the project, each enriched with its latest run per AI model (full answer, brandMentioned, mentionPosition — order the brand was named in the answer, 1 = first, null = not mentioned — with mentionedBrandCount, citedUrl, searchTerms — the web searches the AI ran, the query fan-out —, visitedUrls — every page the AI actually opened, competitors included —, urlVisitRate, sentiment, mentionedBrands, mentionedBrandSentiments, runAt). Response includes `total` (project-wide count) and `returned` (paged count). Core tool for diagnosing AI-visibility gaps, e.g. which prompts mention the brand late.
list_prompts
Lists the Ayzeo projects available to you over MCP — projects you are a member of whose owner holds an active Pro/Enterprise (or trial) subscription — with your role (owner/admin/editor/viewer) and a dashboard link. Use the returned project id as the projectId argument for other tools. If the list is empty, the response carries a message explaining why. Read-only.
list_projects
Runs an ad-hoc prompt search across the configured AI search pipeline and returns the full answer text, cited URLs, and search results. Counts against the project's daily AI-visibility-check quota (plan-dependent).
run_ai_visibility_check
Triggers a fresh run of a saved prompt by ID. Returns the same rich payload as run_ai_visibility_check plus the promptId — enables before/after comparisons after the user implements a content change. Counts against the project's daily AI-visibility-check quota (plan-dependent).
run_prompt
Triggers a fresh full website analysis for the project domain. Optionally accepts a URL (must belong to the project domain).
run_website_analysis
 Recommended guideHow to get your ChatGPT Plugin suggestedFollow the practical steps agents use to find, shortlist, and choose your Plugin.Read guide
Ayzeo ChatGPT Plugin FAQ
How the directory, categories and Discoverability Score work.
Read the methodologyHow do I improve Ayzeo's ChatGPT Plugin discoverability?
The levers are the listing surface agents actually read: names, descriptions, keywords, tool metadata, and registry health. Which lever matters depends on where discovery breaks, which is what continuous measurement shows.
Where is this profile measured?
This profile uses the geography attached to the latest public registry snapshot: US. Locale tags are intentionally omitted.