
- Brand
- Usable
- Category
- AI
- Primary Subcategory
- Enterprise Knowledge Search & AI Context Layer
Integration details
Description
Usable turns what your organisation learns into shared memory that people and approved AI can build on—across tools and models.
- Integration type
- Plugin
- Verification status
- Not applicable
- Platform
- ChatGPT
- Primary Subcategory
- Enterprise Knowledge Search & AI Context Layer
- Secondary Subcategories
- None listed
- Brand
- Usable
- Access
- Account required
- First tracked
- 2026-10-09
- Tool count
- 34
- Geography
- US
The Primary Subcategory used for this profile’s headline score.
Other Subcategories where the Integration is listed.
 Agent Discoverability
 ChatGPT Plugin Discovery Score
Your score is coming
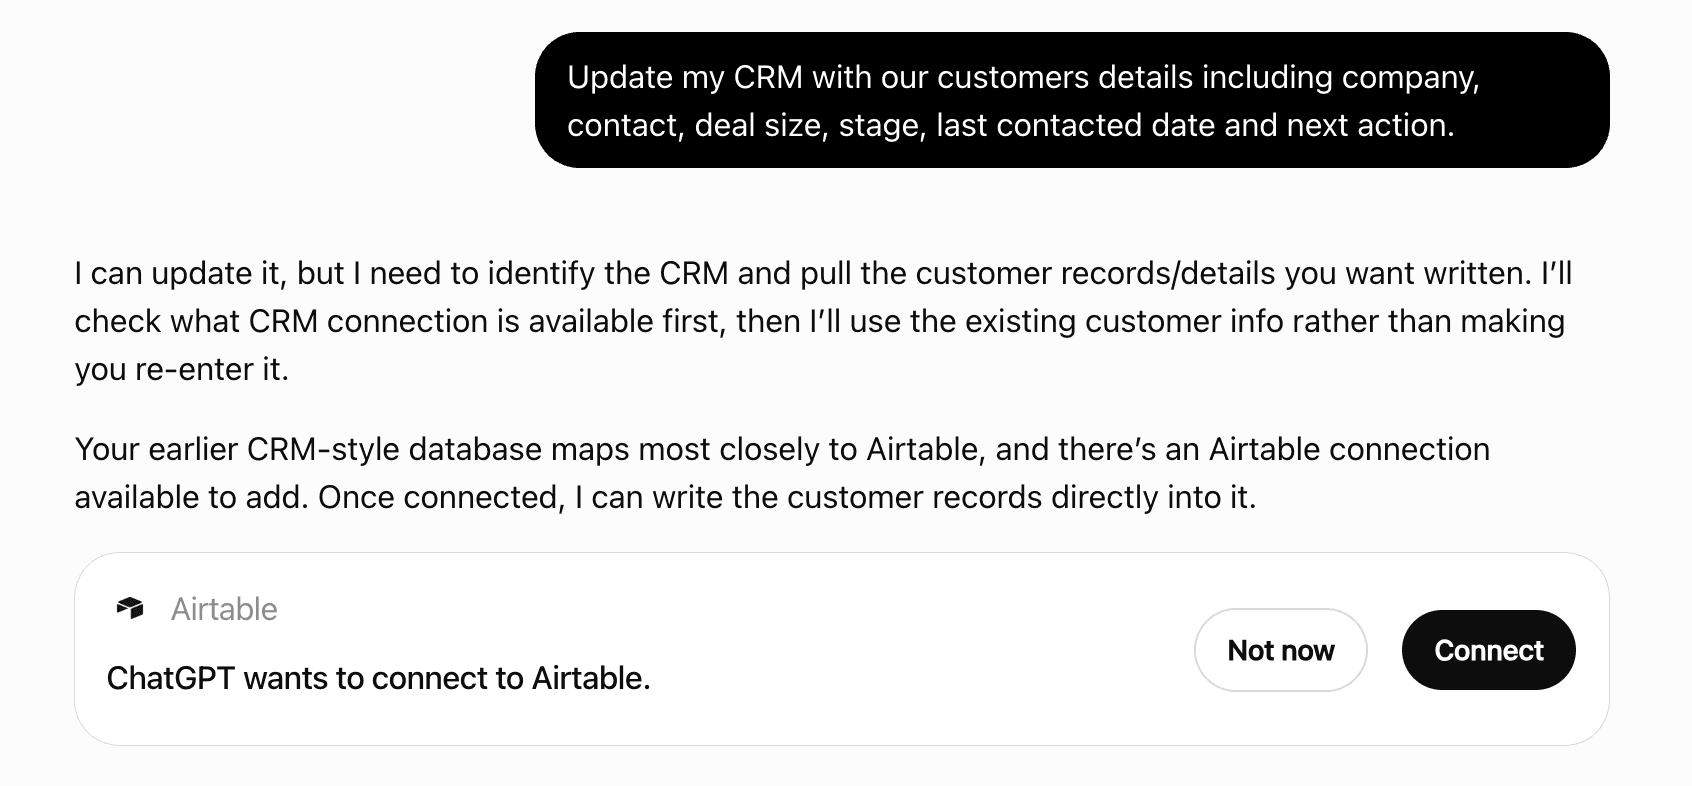
ChatGPT now suggests Plugins on its own when they match a user's request.Your Plugin Discovery Score measures how often yours appears, and it will show here as soon as it’s ready.
What discovery looks like
Get alerts for Usable
Get updates when Usable’s Discoverability Score or category rank changes.
Competing in ChatGPT Enterprise Knowledge Search & AI Context Layer
View Category34 tools agents can invoke
Returns data without cards; only explicit visual requests use `view-memory-fragments`. Primary discovery tool using vector-based semantic search (understands meaning, not keyword matching)—run it before starting work, when resuming, and any time context feels thin. Provide workspace scope (`workspaceId` or `workspaceIds`) and include `repo:<name>` tags when they help focus results (drop them if coverage is lacking). Use `searchIntent`, `context`, and related fields to spell out what you're trying to accomplish so the search can adapt (quick lookup vs. deep research). If the tool returns `decision: NO_RESULTS`, no relevant fragments were found—use the `suggestedQueries` array to retry with different search terms immediately. If the tool returns `decision: NEED_MORE`, adjust inputs or intent and rerun until it's satisfied before executing work, but stop once `invocationLimitReached` flips to true and document the uncovered gaps instead of looping. Reset the invocation attempt counter whenever you pivot to a substantively different search objective. Summarize selected fragments back to the user and always fetch full content with `get-memory-fragment-content` before relying on any returned fragment so you have complete context. Use `collectionId` to scope results to a specific collection. Use `recencyWeight` (0–1) to bias toward recently updated fragments for time-sensitive queries (0 = pure similarity, 1 = pure freshness). **Important:** Always phrase `query` and `searchIntent` as natural language—describe what you need as if talking to a knowledgeable colleague, not a keyword search engine.
agentic-search-fragments
Attach a file to a memory fragment. The file must exist and be accessible. The fragment must exist and the user must have update permissions.
attach-file-to-fragment
Close a dataset query session and release its execution resources. This does not delete the dataset or the original file.
close-tabular-fragment
Create a new collection in a workspace to organize memory fragments into logical groups. Collections have unique names within a workspace. **Required permission:** `fragments.create`.
create-collection
Create a read-only symlink of a fragment in another workspace. The child fragment will auto-sync when the parent is updated and will be cascade-deleted when the parent is deleted. Requires owner/collaborator in both source and target workspaces. **Required permission:** `fragments.update`. If the source type is absent in the target, `workspace.manage_fragment_types` is also required.
create-fragment-symlink
Create a custom fragment type in a workspace. Changes are processed asynchronously (returns status 'processing'). Use get-fragment-types to list existing types first and avoid duplicates. **Required permission:** `workspace.manage_fragment_types` (owner role).
create-fragment-type
Document verified insights, implemented changes, and proven solutions as soon as they're confirmed. Include repository context, apply the Fragment Type Selection Guide, and surface residual risks in the content. **YAML frontmatter support**: Content can include YAML frontmatter (between `---` delimiters) which will be automatically extracted and stored as searchable metadata. Frontmatter can be queried using JSONB operators in `list-memory-fragments` (e.g., `frontmatter ? 'author'` or `frontmatter->>'version' = '1.0'`). **Required permission:** `fragments.create`.
create-memory-fragment
Create a new workspace to organize memory fragments and collaborators. If you belong to an organization the workspace is created under it; otherwise it is a personal workspace. Creation is processed asynchronously (returns status 'processing'). **Required permission:** `workspace.create` (owner role).
create-workspace
Get details of a specific collection by ID. Returns collection metadata including name, description, and timestamps. Optionally includes a paginated list of fragments in the collection when `includeFragments` is true. **Required permission:** `workspace.read`.
get-collection
Get file metadata by ID. By default, includes a short-lived (5-minute) presigned download link. **Security:** the download link is a single-use secret — relay it directly to the requesting end-user, never log it, never include it in long-lived summaries, and never share it with other agents or sessions. Files are stored in Azure Blob Storage, so download links are used instead of returning file content to avoid filling the context window.
get-file
List active fragment types in the single required workspaceId, which must be accessible to the connected account. Returns each type's ID, name, description, icon, color, and default flags. Returns an empty list when that workspace has no active types; does not search other workspaces, create types, or validate a supplied fragment type ID. **Required API Token Permission:** `workspace.read`.
get-fragment-types
Retrieve explicit deterministic linked_to edges on every serving plane. Hosted-zone Leaf additionally returns authorized projected symlink relations; inspect provenance.connectionType to distinguish them. Supports outgoing references, incoming backlinks, or both, with deduplicated results. Required API Token Permission: fragments.read.
get-linked-fragments
Retrieve data for reading, summarizing or analysis without displaying a card. Only explicit visual requests use `view-memory-fragment`. Retrieve fragment content by fragmentId (workspace access) or shareId (named recipient access to one fragment). A shared read returns title, content, and revisionToken only. Optional startLine/endLine or offset/limit enable partial reads. **Required scope:** `fragments.read`.
get-memory-fragment-content
Get metadata and a short-lived download URL for the exact original file uploaded to a dataset fragment. The file is not converted and this operation does not run a query or consume query credits. The URL is a bearer secret for the requesting user only and must not be logged, persisted, summarized, or shared.
get-tabular-fragment-source
List collections in a workspace with pagination. Returns collection metadata ordered by creation date (newest first). **Required permission:** `workspace.read`.
list-collections
**Primary data-only tool for listing, finding, and searching memory fragments.** Ordinary listing does not request cards. Only explicit visual requests use `view-memory-fragments`. Use this tool when users ask to 'list fragments', 'find all fragments', 'show me fragments', 'get fragments', 'search fragments', or query fragments. Provides powerful SQL-like query capabilities with flexible date format support. Returns metadata only (title, summary, tags, dates, author, fragment type) without full content - use `get-memory-fragment-content` to fetch full content by ID. **Capabilities:** - **SQL-like queries**: Full SQL-like filtering with operators: `=`, `!=`, `>`, `<`, `>=`, `<=`, `LIKE`, `ILIKE`, `IN`, `NOT IN`, `@>` (JSON array/object contains), `?` (key exists), `?&` (all keys exist), `?|` (any key exists), `->` (get JSON field), `->>` (get JSON field as text). All filtering is done through the `query` parameter. Example: `status = 'active' AND fragment_type_id = 'uuid' AND tags @> ARRAY['nextjs'] AND created_at >= '2025-01-01'` or `frontmatter @> '{"author": "John"}'` - **Flexible date formats**: Automatically converts multiple date formats to ISO 8601: ISO strings (`'2024-01-15T00:00:00Z'`), dates only (`'2024-01-15'`), timestamps (`1705276800000`), or human-readable (`'2024-01-15 10:30:00'`, `'2024/01/15'`). Use date comparisons in queries: `created_at >= '2025-01-01'` or `updated_at < '2025-11-01T00:00:00Z'` - **Operator precedence**: Follows standard SQL precedence where AND has higher precedence than OR. Example: `status = 'active' AND tags @> ARRAY['a'] OR tags @> ARRAY['b']` is interpreted as `(status = 'active' AND tags @> ARRAY['a']) OR (tags @> ARRAY['b'])`. **Tip:** When in doubt about precedence in complex queries, use parentheses to explicitly group conditions. - **Format guidelines**: Use single quotes for string literals (e.g., `'active'`, `'%test%'`). For dates in queries, use any recognized format - they will be automatically normalized. - **Complex queries**: Supports nested conditions with parentheses, AND/OR operators, date ranges, tag filtering, text search (ILIKE for case-insensitive), status filtering, fragment type filtering, and combinations. Example: `(status IN ('active', 'stale') OR status = 'archived') AND fragment_type_id = 'uuid' AND title ILIKE '%MCP%' AND created_at >= '2025-10-01'` - **Default behavior**: If no `query` is provided, returns fragments with status 'active' or 'stale' (excludes archived). To include archived, use `status IN ('active', 'stale', 'archived')` in your query. - **ORDER BY**: Sort results by `created_at`, `updated_at`, or `title` with `ASC`/`DESC`. Example: `created_at DESC` or `title ASC` - **Pagination**: Use `limit` (1-100, default: 20) and `offset` (default: 0) for pagination **Allowed query columns:** `id`, `fragment_type_id`, `title`, `summary`, `status`, `created_by`, `created_at`, `updated_at`, `tags`, `frontmatter` (Note: `workspace_id` is NOT allowed - workspace filtering is enforced separately for security) **Examples:** - `status IN ('active', 'stale')` - Status filtering - `fragment_type_id = '04a5fb62-1ba5-436c-acf7-f65f3a5ba6f6'` - Filter by fragment type - `tags @> ARRAY['repo:usable', 'mcp']` - Tag array contains (AND logic) - `title ILIKE '%test%'` - Case-insensitive text search - `created_at >= '2025-10-01T00:00:00Z' AND updated_at < '2025-11-01T00:00:00Z'` - Date ranges with timestamps - `created_at >= '2025-10-01'` - Date only (automatically converted) - `created_at >= '1705276800000'` - Timestamp format (automatically converted) - `(status = 'active' AND title ILIKE '%MCP%') OR tags @> ARRAY['mcp']` - Complex nested queries - `status = 'active' AND fragment_type_id = 'uuid' AND tags @> ARRAY['nextjs']` - Multiple conditions - `frontmatter @> '{"author": "John"}'` - JSON object contains - `frontmatter ? 'author'` - Key exists in frontmatter - `frontmatter ?& ARRAY['author', 'version']` - All keys exist - `frontmatter ?| ARRAY['author', 'version']` - Any key exists - `frontmatter->>'author' = 'John'` - Get field as text and compare - `frontmatter->'tags' @> ARRAY['important']` - Nested array search **Required API Token Permission:** `fragments.read`
list-memory-fragments
List all accessible workspaces with role information, permissions, and metadata. Shows owned workspaces (full control) and invited workspaces (based on assigned role). Essential for understanding available knowledge contexts. **Required API Token Permission:** `workspace.read`.
list-workspaces
Create, inspect, update, and manage OAuth credentials for marketplace applications. Use `action` to select the operation. **Actions:** - `list` — List all applications you own or admin - `get` — Get one application's full non-secret OAuth configuration (admin only) - `get-mcp-profile` — Get the app's MCP endpoint and shared-identity policy (admin only) - `create` — Register a new marketplace application with OAuth config - `update` — Update metadata, developer, branding, install access policy, token config, or OAuth configuration (admin only). Use `changes.branding` for invite branding (logoUrl, primaryColor, fromName, replyTo, loginUrl) and the account creation return origin (signupReturnOrigin); provided keys merge into the stored branding and null clears a key. Use `changes.accessControl` to change the install access policy (public, invite-only, approval-required, or workspace-restricted). Use `changes.oauthUrlPatch` for URL-only edits; it defaults to additive so production URLs are preserved, and `updateMode: "replace"` replaces each provided array. Use `changes.oauthConfig` to submit a full replacement config, which is required to change `applicationType` or `grantTypes` - `update-permissions` — Replace requested OAuth scopes using permissions, including fragments.delete with custom: false (admin only). Preserve existing scopes in the list. Active or beta apps require release.version and release.changelog. - `update-mcp-profile` — Fully replace the app's MCP endpoint and shared-identity policy using `mcpProfile` (admin only). Read the current profile first when preserving advanced overrides, then call `get-mcp-profile` after the accepted write to verify persisted values. Disabling blocks existing gateway calls; configuration changes require gateway owners to remove and re-add the app - `reveal-credentials` — Explicitly return the current client ID and secret without rotation (admin only; secret-bearing) - `regenerate-credentials` — Explicitly rotate and return credentials; the previous secret is immediately invalid (admin only; secret-bearing) - `installation-spend-status` — Inspect configuration prerequisites without secret material - `emergency-revoke-installation-spend` — Revoke every installation credential using app-admin authorization - `list-webhooks`, `create-webhook` (`webhook.url`, `webhook.events`; returns the signing secret once), `delete-webhook`, `test-webhook` (`webhookId`) — Manage app webhooks (admin only) - `list-versions`, `publish-version` (`release.version`, `release.changelog`, `release.breakingChange`) — Version history and releases (admin only) - `list-admins`, `invite-admin` (`adminInvite`), `change-admin-role` (`targetUserId`, `adminRole`), `remove-admin` (`targetUserId`), `revoke-admin-invite`, `resend-admin-invite` (`inviteId`) — Manage app admins and viewers (admin only) - `list-installations` (`installationStatus`: installed or pending), `approve-installation`, `deny-installation` (`targetUserId`) — Review install requests for approval-required apps (admin only) **Required API Token Permission:** `fragments.create` for ordinary application actions. Secret-bearing `reveal-credentials` and `regenerate-credentials` actions additionally require `workspace.update`. Installation-spend actions reject personal access tokens and require a user session plus application-admin authority in Core; emergency revoke is destructive.
manage-application
Inspect and control installation-bound background credit authority. Actions: status, list, approve, rotate, revoke. Core enforces installer or organization billing authority for each installation. approve/rotate create an app-redeemable one-time approval and return lifecycle metadata only. Responses never contain credential secrets, client secrets, or JWTs.
manage-installation-spend-credential
Open an authorized, expiring query session for a ready dataset. Pass a returned sessionId to load another fragment from the same workspace. Returns every loaded fragment and collision-safe SQL table alias. Requires individual opt-in and an eligible subscription; data survives container sleep.
open-tabular-fragment
Run bounded read-only SQL over every fragment loaded into a dataset session. This consumes configured credits. Reuse requestId and exact arguments on retries. Returns at most 500 rows and 1 MiB; use aggregates or pagination for larger datasets. Access to every loaded fragment, opt-in and budget are checked for each operation.
query-tabular-fragment
Remove a symlinked fragment by deleting the child copy. Requires owner/collaborator in the parent workspace. **Required permission:** `fragments.delete`.
remove-fragment-symlink
Request a short-lived, workspace-scoped import grant for hash-exact Markdown, HTML or tabular fragment creation (CSV, XLS, XLSX, XLSM, DuckDB, Parquet). Tabular files normalize asynchronously and require explicit opt-in and an eligible subscription. The document bypasses model context and is streamed unchanged to the returned HTTPS endpoint. The grant binds fragment metadata, byte size, SHA-256, user, workspace, and expiry. **Required permission:** `fragments.create`.
request-fragment-import
Generate a presigned upload URL for file uploads. Returns a URL that the user can upload to directly via curl/HTTP. The LLM should then poll with get-file(fileId) to check upload status.
request-upload-url
Search for files in a workspace by keyword, tags, or MIME type. Returns file metadata without file content.
search-files
Returns data without cards; only explicit visual requests use `view-memory-fragments`. Fallback vector-based semantic search (understands meaning, not keyword matching). Use only when `agentic-search-fragments` errors or cannot reach a workspace. Provide the relevant workspace scope; add `repo:<name>` tags when they help narrow results and drop them if coverage is lacking. Review similarity scores and timestamps, then pivot back to the agentic tool for iterative expansion. Always fetch full fragment content with `get-memory-fragment-content` before relying on any returned fragment so you have complete context. Use `recencyWeight` (0–1) to bias toward recently updated fragments (0 = pure similarity, default). **Required permission:** `fragments.read`.
search-memory-fragments
Search the public workspace registry — discover public workspaces you are not yet a member of or subscribed to, ranked by full-text relevance over name and description, with pagination. Use `subscribe-to-workspace` to subscribe to a result. **Required API Token Permission:** `workspace.read`.
search-public-workspaces
Subscribe to a public workspace to gain read-only access to its memory fragments. Use `search-public-workspaces` to discover workspace IDs. Subscription is processed asynchronously (returns status 'processing'). Only public workspaces you are not already a member of can be subscribed to. **Required permission:** `workspace.subscribe`.
subscribe-to-workspace
Update a collection's name or description. At least one field must be provided. Collection names must remain unique within the workspace. **Required permission:** `fragments.update`.
update-collection
Update a custom fragment type's name, description, icon, or colour. System default fragment types cannot be modified. Changes are processed asynchronously (returns status 'processing'). **Required permission:** `workspace.manage_fragment_types` (owner role).
update-fragment-type
Update a workspace fragment by fragmentId, or update only content on a named-user Editor share with shareId and the revisionToken from get-memory-fragment-content. Shared edits support content or patchOperations and cannot change metadata, type, or collections. **Required scope:** `fragments.update`.
update-memory-fragment
Update an existing workspace's name, description, visibility, or trusted HTML runtime policy and exact HTTPS resource allowlists. Use htmlRuntime.resources.script/style/image/font/connect to configure allowed origins. Workspace-wide script execution requires confirmWorkspaceScripts=true. Changes are processed asynchronously (returns status 'processing'). **Required permission:** `workspace.update` (owner role).
update-workspace
Use only when the user explicitly asks to view a fragment visually or display a fragment card. Ordinary read, fetch, summarize or analyze requests use `get-memory-fragment-content`. Reuses that tool's selectors, partial reads and access restrictions. Named-share reads disclose only the existing restricted shared result. Leaf supports local fragmentId or key plus workspaceId reads; shareId and partial reads require Cloud. **Required scope:** `fragments.read`.
view-memory-fragment
Use only when the user explicitly asks to display fragment cards or a visual table. Ordinary list, filter, count, search or analyze requests use `list-memory-fragments` or the search tools. Reuses list filtering, ordering and pagination with complete rows; select and groupBy are rejected. To display chosen search results on Cloud, filter by their exact returned IDs, e.g. query: id IN ('uuid-1', 'uuid-2'). Leaf requires workspaceId and supports unfiltered pagination only; query/orderBy require Cloud. **Required scope:** `fragments.read`.
view-memory-fragments
 Recommended guideHow to get your ChatGPT Plugin suggestedFollow the practical steps agents use to find, shortlist, and choose your Plugin.Read guide
Usable ChatGPT Plugin FAQ
How the directory, categories and Discoverability Score work.
Read the methodologyHow do I improve Usable's ChatGPT Plugin discoverability?
The levers are the listing surface agents actually read: names, descriptions, keywords, tool metadata, and registry health. Which lever matters depends on where discovery breaks, which is what continuous measurement shows.
What are Usable alternatives on ChatGPT?
As of 2026-10-09, Usable competes with Algolia Productivity, Analytics Brain, Archiveye, Atlan, BitsWeave, BuildBetter.ai, Business Helper, CERTENTIC Bridge and 44 more in ChatGPT Enterprise Knowledge Search & AI Context Layer, ranked by public Discoverability Score.
Where is this profile measured?
This profile uses the geography attached to the latest public registry snapshot: US. Locale tags are intentionally omitted.