mcp.riveterhq.com
Get structured web data - search, scrape, and extract data, or build and enrich large datasets easily
- Category
- AI
- Primary Subcategory
- Web Search, Crawling & Extraction for Agents
 View in the Claude registry
Integration details
Description
Riveter turns web research into structured data. Give Claude a list of companies, people, or URLs and ask for new columns: product descriptions, revenue, deep analysis, company headcount, link traces, pricing, tech stack analysis, contact details, a classification, a summary, etc. Riveter runs an AI agent per row that searches, reads pages, and fills in each cell with a sourced answer. What you can do - Enrich rows you already have. Paste a list or point at a saved enrichment and get the new columns back. Up to 10,000 rows per run. - Build a list from a description. "Every lawfirm in Indiana", "every YC W24 company in healthcare", "competitors of Stripe". Riveter generates the rows, and can enrich them in the same run. - Scrape a page. Clean text or markdown from any URL, including JavaScript-rendered pages. - Search the web. One-shot search results, or a research agent that answers a question with a structured, schema-shaped response. - Extract records from a site. Define the fields you want and pull them from listings, directories, or catalogs as JSON. - Monitor for changes. Run a saved enrichment daily, weekly, or monthly and get alerts or webhooks when values change. How it works Long runs are asynchronous. Claude starts the run, checks status, and fetches results when they are ready. Every run has an id you can come back to later, and results stay available in your Riveter account. Setup Click Connect and sign in to your Riveter account. Riveter creates an API key for this connection; you can revoke it at any time from Settings → API to disconnect. Runs use credits from your Riveter plan. Free accounts include trial credits. Read-only tools (status, results, listings) are marked read-only. Tools that start runs or change saved configuration are marked as writes. Stopping a run and pausing a monitor are marked destructive. Docs: https://docs.riveterhq.com
- Integration type
- Connector
- Verification status
 Community connector
- Platform
- Claude
- Primary Subcategory
- Web Search, Crawling & Extraction for Agents
- Secondary Subcategories
- None listed
- Brand
- Riveter
- Access
- Account required
- First tracked
- 2026-09-03
- Tool count
- 26
- Geography
- US
The Primary Subcategory used for this profile’s headline score.
Other Subcategories where the Integration is listed.
Claude Discoverability Score
Claude Connector discovery is coming soon
Community Connectors only appear in Claude’s registry.Once verified, organic discovery begins and we can calculate your score.Read more about Community Connector verification.
No spam. Unsubscribe any time.
No spam. Unsubscribe any time.
What discovery looks like
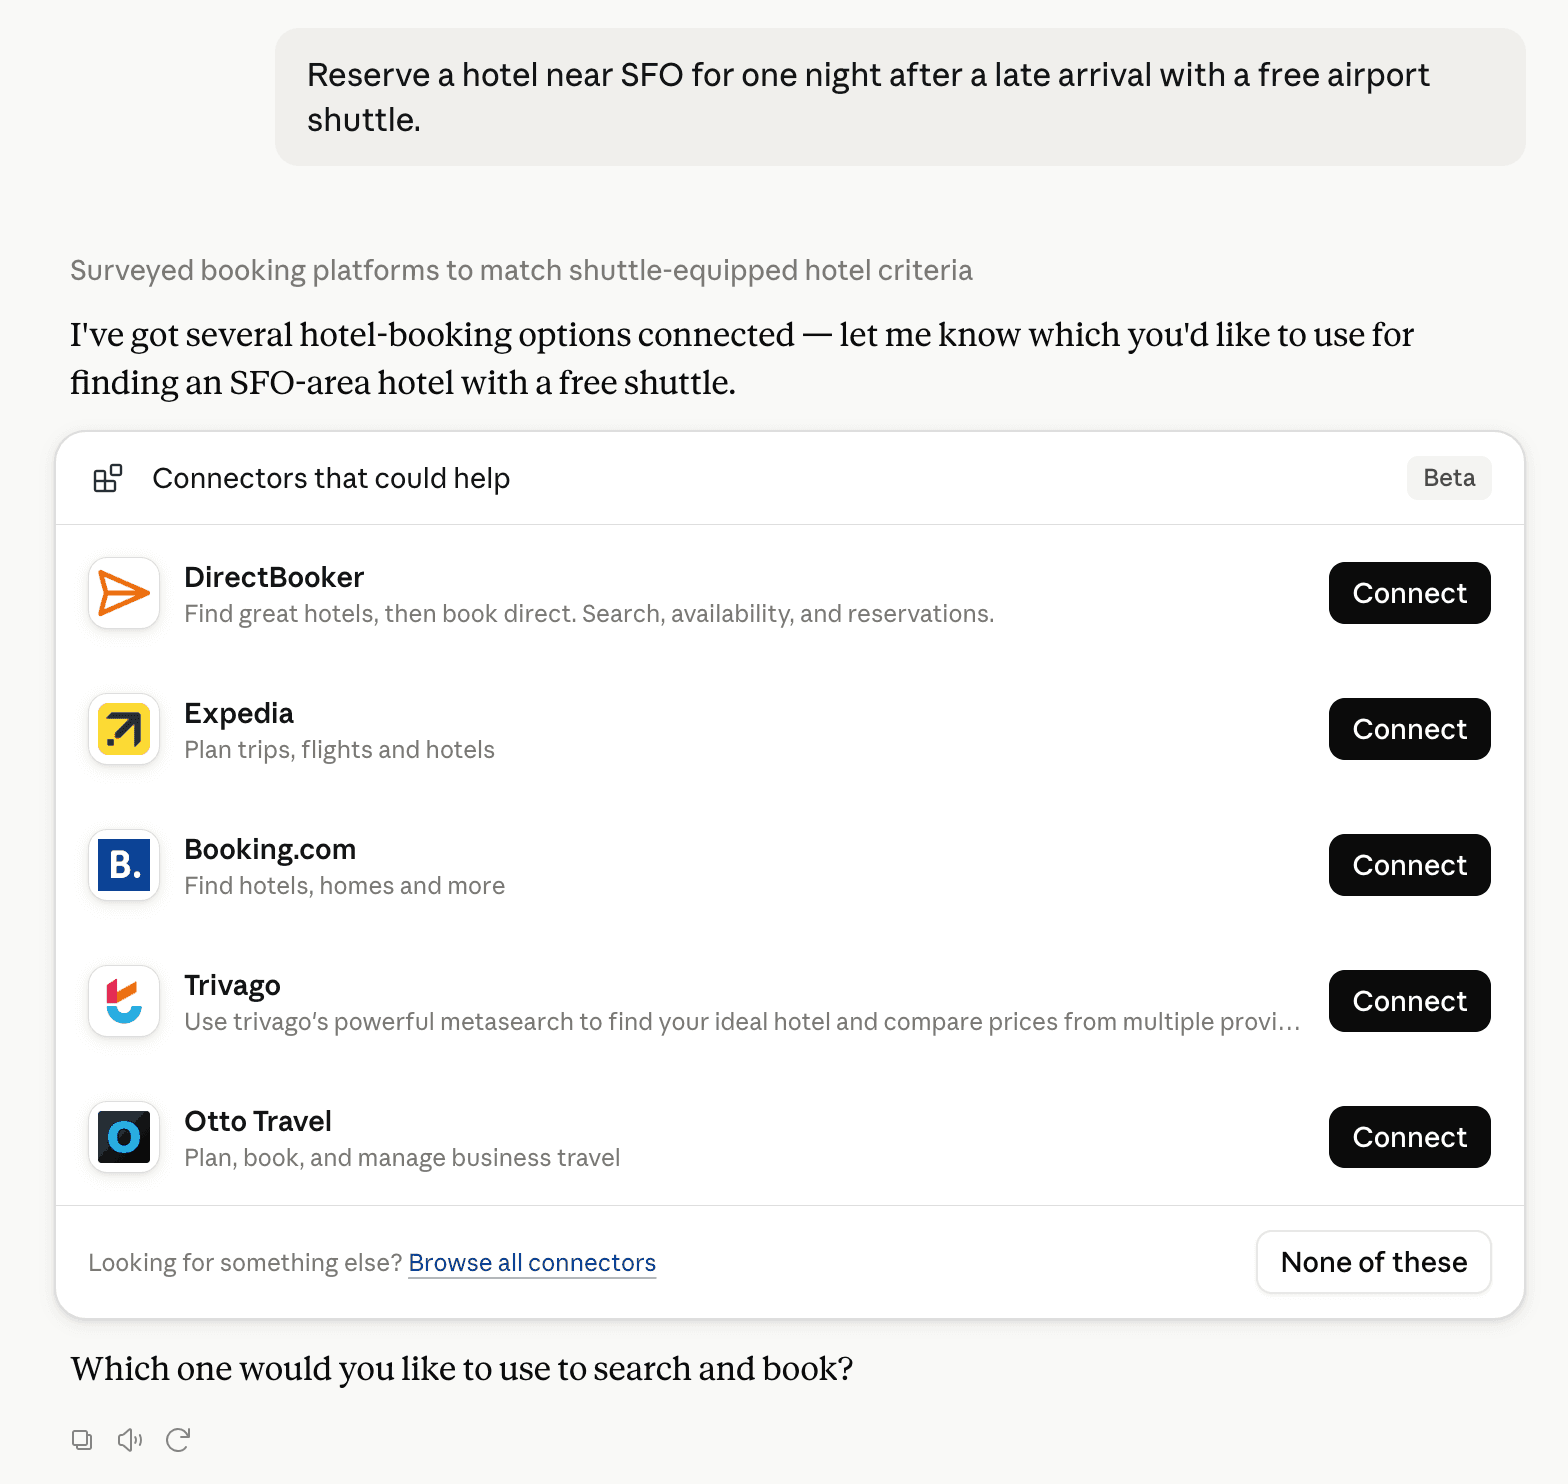
Claude can surface verified Connectors when they match a user’s Prompt.
How Claude Connector discovery works
Your Connector will compete to appear for users’ Prompts once Claude verifies it
Competing in Claude Web Search, Crawling & Extraction for Agents
View Category26 tools agents can invoke
How do I improve a Community connector's discoverability?
The levers are the listing surface agents actually read: names, descriptions, keywords, tool metadata, and registry health. Which lever matters depends on where discovery breaks, which is what continuous measurement shows.
What are mcp.riveterhq.com alternatives on Claude?
As of 2026-09-15, mcp.riveterhq.com competes with Firecrawl, Ahrefs, Exa, Nimble, Parallel Search, Tavily, TinyFish, Anakin, Cala, Context.dev, Keenable SELECT, Keenable Web Search, Parliament Connect, Scry, Seltz, Sequentum MCP, Sonar Connections, TubeAlfred, You.com in Claude Web Search, Crawling & Extraction for Agents, ranked by public Discoverability Score.
Where is this profile measured?
This profile uses the geography attached to the latest public registry snapshot: US. Locale tags are intentionally omitted.